
Python
Use NumPy images with the Python API to detect faces, extract features and run optional analysis. The Get started example reads an image and saves the detection result.
Install
python -m pip install inspireface opencv-python
The current PyPI release is 1.2.4.post3, with the 1.2.4 CPU runtime included. It provides detection, recognition, analysis, snapshots, capture and diagnostics without a separate SDK build. If InspireFace is already installed, upgrade with python -m pip install --upgrade inspireface.
Wheels are available for Windows x64, Linux x86_64 / ARM64 and macOS Intel / Apple Silicon. The current macOS native libraries require macOS 14+ on arm64 and 15+ on Intel; see package downloads for the platform files and wheel-tag details. Models are downloaded on first use or loaded from a local resource pack.
Windows uses the same API and examples below. Use x64 Python; the published wheel runs CPU inference and includes libInspireFace.dll. If a DLL dependency is missing, install the Microsoft Visual C++ v14 Redistributable for x64 and retry. See Windows loading errors for diagnostics.
Initialize once and reuse the session
import cv2
import inspireface as isf

image = cv2.imread("face.jpg")
if image is None:
    raise FileNotFoundError("face.jpg")

isf.launch("Pikachu")  # Downloads the model on first use.
session = None
try:
    session = isf.InspireFaceSession(
        isf.HF_ENABLE_FACE_RECOGNITION | isf.HF_ENABLE_QUALITY,
        isf.HF_DETECT_MODE_ALWAYS_DETECT,
        max_detect_num=10,
        detect_pixel_level=320,
    )
    faces = session.face_detection(image)
    for face in faces:
        print(face.location, face.detection_confidence)
finally:
    if session is not None:
        session.release()
    isf.terminate()
The first launch("Pikachu") downloads the model if needed. For a model already on disk, use launch(resource_path="/path/to/Pikachu"). The finally block releases the session even when processing fails.
For a camera, create the session outside the frame loop. Use one session per independent sequence or worker and keep processing on that session ordered.
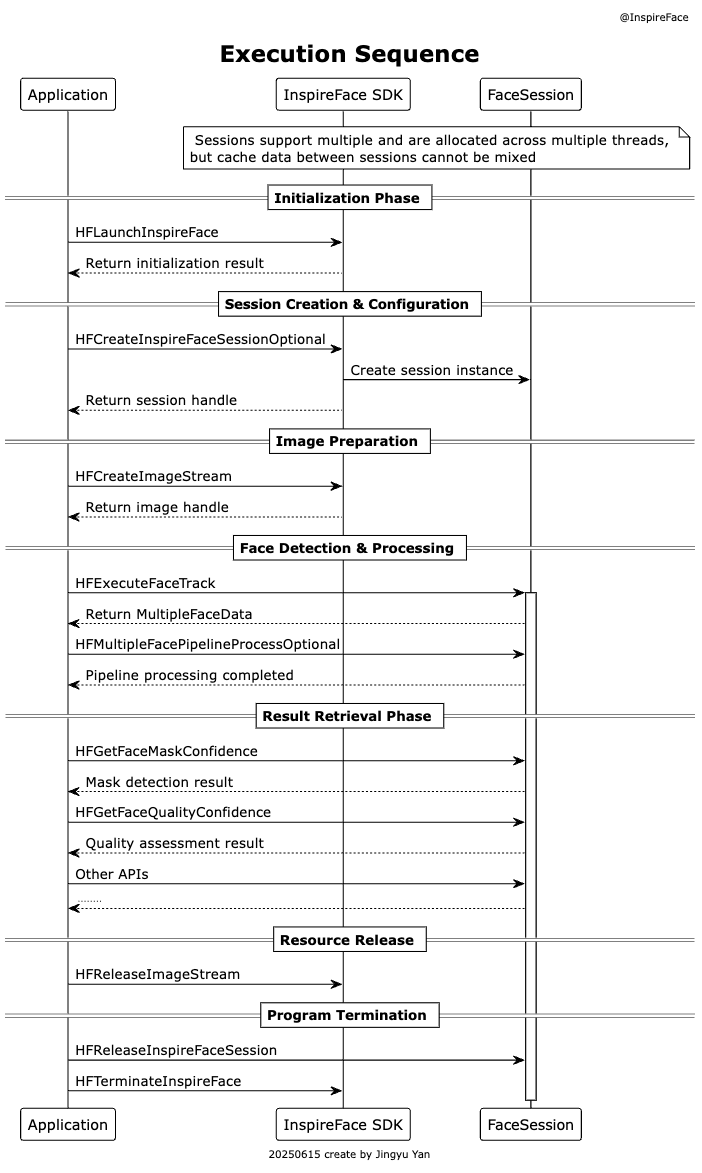
For video, repeat the per-frame work and keep the session open. Close it when the worker finishes, then call terminate() after all sessions have closed. Each worker processes its own session in order.
Detection results
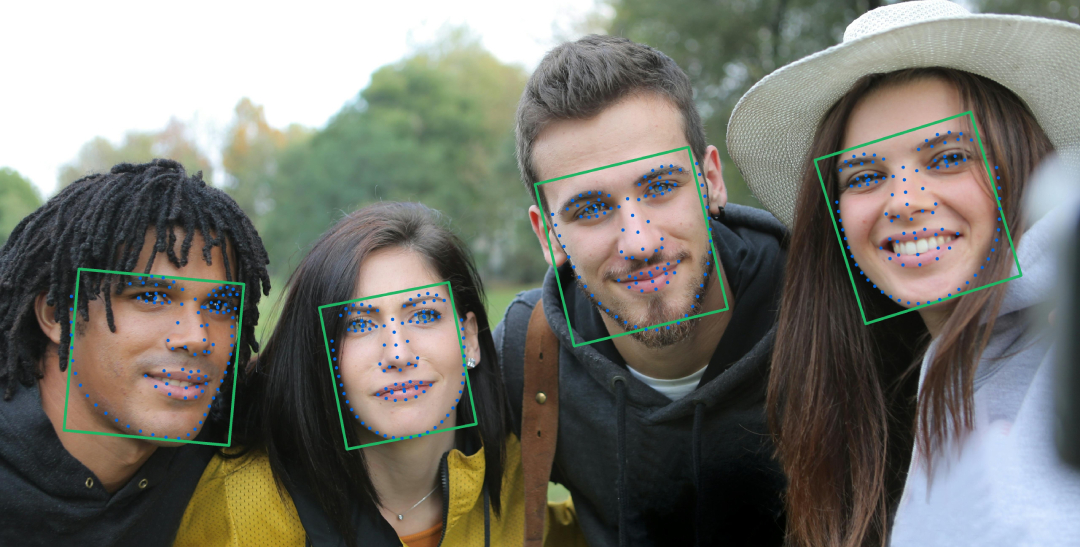
face_detection accepts an image array or an ImageStream and returns a list. An empty list means that no face passed detection.
| Field | Meaning |
|---|---|
location | (x1, y1, x2, y2) box; width is x2 - x1. |
detection_confidence | Detection score. |
track_id | ID used to follow a face within one tracking session. |
track_count | Tracker count used by temporal policies such as capture. |
roll, yaw, pitch | Pose fields; enable HF_ENABLE_FACE_POSE when you need them. |
The wrapper copies each face token into Python-owned storage. Retain the matching source image alongside it for later feature extraction or pipeline calls.
Optional Analysis
Enable an option at session creation and request it again when running the pipeline:
options = isf.HF_ENABLE_QUALITY | isf.HF_ENABLE_MASK_DETECT
session = isf.InspireFaceSession(options)
try:
    faces = session.face_detection(image)
    if faces:
        results = session.face_pipeline(image, faces, options)
        for face, result in zip(faces, results):
            print(face.location, result.quality_confidence, result.mask_confidence)
finally:
    session.release()
The SDK is already launched in this block, and image is a BGR array. Request a subset of the session's enabled options, then read those fields from the returned list in input-face order.
| Flag | Fields in each FaceExtended |
|---|---|
HF_ENABLE_QUALITY | quality_confidence |
HF_ENABLE_MASK_DETECT | mask_confidence |
HF_ENABLE_LIVENESS | rgb_liveness_confidence |
HF_ENABLE_INTERACTION | left_eye_status_confidence, right_eye_status_confidence, action_normal, action_blink, action_jaw_open, action_shake, action_head_raise |
HF_ENABLE_FACE_ATTRIBUTE | race, gender, age_bracket |
HF_ENABLE_FACE_EMOTION | emotion |
Attribute and expression label order
Map the returned category indices to the arrays below after checking the index range. These labels describe the model's predictions from the input image.
race_labels = ["Black", "Asian", "Latino/Hispanic", "Middle Eastern", "White"]
gender_labels = ["Female", "Male"]
age_labels = ["0–2", "3–9", "10–19", "20–29", "30–39", "40–49", "50–59", "60–69", "70+"]
emotion_labels = ["Neutral", "Happy", "Sad", "Surprise", "Fear", "Disgust", "Anger"]
For complete per-feature examples and result interpretation, see Optional analysis.
Face RGB Anti-Spoofing
Request HF_ENABLE_LIVENESS and read rgb_liveness_confidence. See liveness detection for a complete flow and threshold considerations.
Face Interactions Action Detection
Request HF_ENABLE_INTERACTION on a tracking session and run the pipeline on consecutive frames. Eye-state scores are close to 1 for open and close to 0 for closed. Use the action events to advance your application's prompts, timeouts and retry flow.
Landmarks and embeddings
# The session has recognition enabled and faces came from image.
if len(faces) == 1:
    five_points = session.get_face_five_key_points(faces[0])
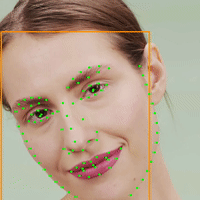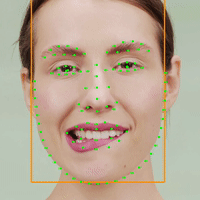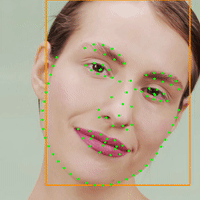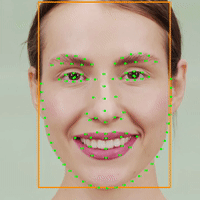
    dense_points = session.get_face_dense_landmark(faces[0])
    embedding = session.face_feature_extract(image, faces[0])
    print(five_points.shape, dense_points.shape, embedding.shape)
Landmarks are arrays of point coordinates. Embeddings are copied NumPy arrays; save the model identity alongside stored vectors. The comparison example shows embedding comparison and threshold handling.
Raw buffers and ImageStream
The PyPI package supports scoped streams: leaving a with block releases the stream, including when processing raises an exception.
Passing a three-channel uint8 array directly uses BGR, as returned by cv2.imread. Four-channel arrays use BGRA. Specify the format when creating a stream from other pixel layouts:
with isf.ImageStream.load_from_cv_image(
    rgb_image,
    stream_format=isf.HF_STREAM_RGB,
    rotation=isf.HF_CAMERA_ROTATION_0,
) as stream:
    faces = session.face_detection(stream)
Use RGB pixels with HF_STREAM_RGB; convert the channel order before creating the stream if your image uses another order. For a tightly packed NV21 buffer:
with isf.ImageStream.load_from_buffer(
    nv21_bytes, width, height,
    isf.HF_STREAM_YUV_NV21,
    isf.HF_CAMERA_ROTATION_0,
) as stream:
    faces = session.face_detection(stream)
NV12, NV21 and I420 require even width and height. The stream retains its input memory; contiguous mutable inputs can be shared without a copy. Keep their size and contents unchanged until processing finishes. Non-contiguous NumPy inputs are copied into contiguous storage. Image inputs covers strides, buffer sizes and rotation.
Snapshots and capture
session.face_detection_snapshot(image) returns an owned snapshot that can also be passed to a face-capture update. Create a new snapshot from each frame to update tracking.
with session.face_detection_snapshot(image) as snapshot:
    for face in snapshot.faces:
        print(face.track_id, face.track_count)
Use face capture to select a stable face and a few suitable frames. Feed frames from your camera worker and retain the images selected by the capture policy.
Handle errors at the application boundary
The wrapper raises typed exceptions for invalid buffers, unavailable features, failed processing and resource errors:
try:
    faces = session.face_detection(image)
except isf.InspireFaceError as error:
    print(error.error_code, error.error_name, str(error))
    raise
Handle an empty face list as a normal detection result and report processing exceptions separately. Include the model pack, native version, input shape and enabled options in error logs.
Use a local native build
For TensorRT, CoreML, Rockchip or a custom CPU build, see Python packaging. Keep the wrapper and native library from the same SDK revision. The PyPI CPU package already includes the library needed for the examples above.
A wheel includes its native library. To use a local build with the 1.2.4 wrapper, set INSPIREFACE_LIBRARY_PATH before importing inspireface:
export INSPIREFACE_LIBRARY_PATH=/absolute/path/to/libInspireFace.so
python -c 'import inspireface as isf; print(isf.version())'
$env:INSPIREFACE_LIBRARY_PATH = 'C:\sdk\InspireFace\lib\libInspireFace.dll'
python -c "import inspireface as isf; print(isf.version())"
On macOS, use the native libInspireFace.dylib from the SDK’s InspireFace/lib/ directory, or build a shared library using the macOS guide. The Objective-C and Swift frameworks are for Apple application targets; they are not a drop-in replacement for this Python library file. The library architecture must match the running Python process. An Intel Python running under Rosetta needs an Intel library even on an Apple Silicon machine.
These commands also work with the installed PyPI wrapper; an editable install is needed only when changing the Python source. On Windows, point to the CPU SDK DLL and keep x64 Python and the x64 runtime together. To return to the bundled library in PowerShell, run Remove-Item Env:INSPIREFACE_LIBRARY_PATH -ErrorAction SilentlyContinue, then restart Python.
Install the backend's runtime dependencies along with the native library. Target-specific setup is covered in Rockchip Python and TensorRT.
Prepare a reproducible environment
Keep the interpreter, Python wrapper, native library and model pack together when recording a working setup. A useful first check is:
python -c 'import platform, sys; print(sys.executable); print(platform.machine())'
python -m pip show inspireface
python -c 'import inspireface as isf; print(isf.version())'
The package metadata reports the Python distribution version; isf.version() reports the loaded native runtime. Record both for a custom build. In notebooks, set the library environment variable before the first import and restart the kernel after changing the selected native library.
| Deployment item | Purpose |
|---|---|
| Virtual environment | Keeps the wrapper and NumPy dependencies separate from other applications. |
| Native library and dependencies | Must match the process architecture and selected backend. |
| Model pack | A readable local file passed as resource_path. |
| Input assets | Test images with a known format and orientation before camera integration. |
Offline deployment
Copy both the Python package and model pack onto an offline target, then pass the local pack path to launch. Keep the pack name and version alongside any saved recognition database.
Complete command-line examples
Detect and save the result
Save this code as detect.py. It prints the detection results and saves an image with face boxes as detected.jpg.
detect.py — Complete code
"""Detect faces in one image and save an annotated copy."""
import argparse
from pathlib import Path

import cv2
import inspireface as isf


def main():
    parser = argparse.ArgumentParser(description=__doc__)
    parser.add_argument("image", type=Path)
    parser.add_argument("--model", type=Path, help="Path to an unpacked resource pack")
    parser.add_argument("--output", type=Path, default=Path("detected.jpg"))
    args = parser.parse_args()

    image = cv2.imread(str(args.image))
    if image is None:
        parser.error(f"Cannot read image: {args.image}")
    if args.model is None:
        isf.launch("Pikachu")  # Downloads the model on first use.
    else:
        isf.launch(resource_path=str(args.model))

    session = None
    try:
        session = isf.InspireFaceSession(
            isf.HF_ENABLE_NONE, isf.HF_DETECT_MODE_ALWAYS_DETECT,
            max_detect_num=10, detect_pixel_level=320,
        )
        faces = session.face_detection(image)
        print(f"Detected {len(faces)} faces")
        output = image.copy()
        for face in faces:
            x1, y1, x2, y2 = face.location
            cv2.rectangle(output, (x1, y1), (x2, y2), (60, 170, 80), 2)
            print(face.location, face.detection_confidence)
        if not cv2.imwrite(str(args.output), output):
            raise RuntimeError(f"Cannot write image: {args.output}")
        print(f"Saved {args.output}")
    finally:
        if session is not None:
            session.release()
        isf.terminate()


if __name__ == "__main__":
    main()
python detect.py /path/to/face.jpg --model /path/to/Pikachu --output detected.jpg
Compare two images
Save this code as compare.py. Each image must contain exactly one face. The program prints the cosine similarity, the model's recommended threshold and whether the score meets that threshold.
compare.py — Complete code
"""Compare two images that each contain exactly one face."""
import argparse
import cv2
import inspireface as isf


def main():
    parser = argparse.ArgumentParser(description=__doc__)
    parser.add_argument("first")
    parser.add_argument("second")
    parser.add_argument("--model", required=True)
    args = parser.parse_args()
    images = [cv2.imread(path) for path in (args.first, args.second)]
    if any(image is None for image in images):
        parser.error("Both image paths must be readable")

    isf.launch(resource_path=args.model)
    session = None
    try:
        session = isf.InspireFaceSession(
            isf.HF_ENABLE_FACE_RECOGNITION, isf.HF_DETECT_MODE_ALWAYS_DETECT,
            max_detect_num=10, detect_pixel_level=320,
        )
        features = []
        for image in images:
            faces = session.face_detection(image)
            if len(faces) != 1:
                raise ValueError(f"Expected exactly one face; found {len(faces)}")
            features.append(session.face_feature_extract(image, faces[0]))
        similarity = isf.feature_comparison(features[0], features[1])
        threshold = isf.get_recommended_cosine_threshold()
        print(f"Cosine similarity: {similarity:.4f}")
        print(f"Model threshold: {threshold:.4f}")
        print(f"Above threshold: {similarity >= threshold}")
    finally:
        if session is not None:
            session.release()
        isf.terminate()


if __name__ == "__main__":
    main()
python compare.py /path/to/first.jpg /path/to/second.jpg --model /path/to/Pikachu
For video processing, see Tracking. For in-memory and persistent galleries, see FeatureHub. Both guides include code examples on the page.